
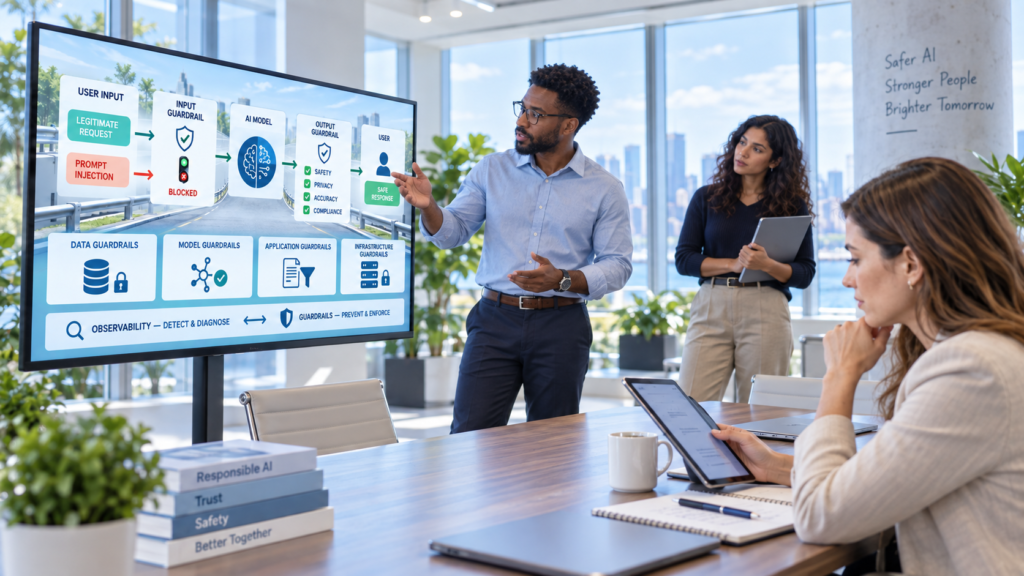
AI guardrails are the safeguards, rules, and technical controls placed around an AI system’s inputs and outputs to keep it operating safely, accurately, and within defined ethical and legal limits. In plain terms: guardrails are what stop an AI system from doing the wrong thing even when a user asks it to, or when it’s tempted to on its own.
IBM describes them with a simple highway analogy: like the physical barriers that keep a vehicle from veering off the road, AI guardrails guide a system’s behavior back on course without stopping it from moving forward at all.[4] Guardrails work alongside AI observability rather than replacing it — observability tells you what an AI system is doing and whether it’s going wrong; guardrails are what actively stop it from going wrong in the first
Enterprise adoption of generative AI and autonomous agents has turned guardrails from a research topic into a fast-growing product category. Market researcher Market.us values the global AI guardrails market at about $0.7 billion in 2024, projecting growth to $109.9 billion by 2034 — a 65.8% compound annual growth rate — with North America currently the largest regional market.[7] Independent testing, however, shows the technology is still maturing: a 2026 comparative study of three major commercial LLM platforms found output-side guardrails caught under 2% of harmful responses that made it past input filters, with the model’s own built-in training alignment doing far more of the actual protective work.[5]
What Are AI Guardrails?
Every AI system, especially one built on a large language model, can be pushed toward outputs its developers never intended — through a malicious prompt, an honest misunderstanding, or simply a question it was never designed to answer. Guardrails are the layer of rules and checks that catch this, either by rewriting or blocking a risky input before it reaches the model, or by screening the model’s output before it reaches the user. A 2024 review of LLM risks and guardrail approaches organizes this into three levels: external protections like system prompts and user-facing controls, secondary defenses such as retrieval-augmented generation that grounds answers in verified sources, and internal safeguards built directly into how the model itself was trained.[3]
What Are the Types of AI Guardrails?
IBM organizes AI guardrails into four practical categories.[4] Data guardrails remove sensitive information and bias from training data before a model ever learns from it. Model guardrails apply fine-tuning, validation, and ongoing monitoring to keep measurable qualities like toxicity and accuracy in check once the model is live. Application guardrails sit at the software layer, using APIs and filtering tools to block harmful content or restrict what an AI tool is allowed to do within a specific workflow. Infrastructure guardrails operate a level below all of this, enforcing access controls, encryption, and monitoring across the cloud and network systems an AI workload runs on.
Why Do AI Guardrails Matter?
The risks guardrails address are concrete and costly. Prompt injection, data leakage, and jailbreak techniques can expose personal information or be turned into tools for phishing campaigns, and IBM’s own 2025 Cost of a Data Breach Report put the average U.S. breach at $10.22 million.[4] A widely cited peer-reviewed toolkit for programmable guardrails frames the underlying problem plainly: safety controls built only into model training are hard to adjust and audit after the fact, whereas separate, inspectable rails let developers change and reason about a system’s boundaries independently of the model itself.[1] Regulatory pressure adds another driver — a 2025 systematic review of 553 peer-reviewed publications on responsible AI identified robustness, accountability, and human oversight as recurring principles that guardrails are one of the few concrete engineering tools available to actually implement.[2]
How Effective Are AI Guardrails?
Independent testing shows real gaps remain. A 2026 comparative study tested three major cloud LLM platforms’ guardrails against 1,123 prompts, most of them ordinary and a minority deliberately malicious.[5] Input filters performed unevenly — one platform blocked over 90% of malicious prompts, while another blocked just 53%, and the most aggressive filter also incorrectly flagged more than 13% of harmless requests, including legitimate code-review and math questions. Output filters performed far worse across every platform tested, catching under 2% of harmful responses that made it through — with the underlying model’s own training alignment blocking the large majority of remaining harmful content on its own. The most effective bypass technique across platforms was simple role-play framing, where a harmful request was wrapped in a fictional scenario.
How Are AI Guardrails Different From AI Observability?
The two are complementary, not interchangeable. AI observability is the practice of collecting telemetry to determine whether an AI system’s outputs are correct, grounded, and safe — it is fundamentally a detection and diagnosis discipline. Guardrails are the enforcement layer: the rules and filters that act on that information, or act independently of it, to stop a bad outcome before it reaches a user. A well-instrumented AI system typically needs both — observability to catch failures like model drift that guardrails aren’t designed to detect, and guardrails to block harmful inputs and outputs in real time that observability alone would only report on after the fact.
Key Takeaways
- AI guardrails are the safeguards and technical controls that keep an AI system’s inputs and outputs within safe, accurate, and legally compliant boundaries, acting before a harmful outcome reaches a user.
- They operate across four practical layers: data guardrails, model guardrails, application guardrails, and infrastructure guardrails.
- Guardrails complement, rather than replace, AI observability — observability detects and diagnoses problems; guardrails actively enforce boundaries.
- Independent 2026 testing found real effectiveness gaps: output-side filters caught under 2% of harmful responses across three major platforms, with a model’s own training alignment doing most of the protective work.
- The global AI guardrails market is projected to grow from about $0.7 billion in 2024 to $109.9 billion by 2034, a 65.8% annual growth rate, reflecting how central this layer has become to enterprise AI deployment.
Frequently Asked Questions
Are AI guardrails the same as content moderation?
Content moderation is one specific application of AI guardrails, focused on filtering harmful or inappropriate content. Guardrails are the broader category, also covering data privacy, factual accuracy, brand and tone consistency, regulatory compliance, and restricting what actions an AI agent is allowed to take — content moderation is a subset, not a synonym.
Can AI guardrails be bypassed?
Yes. Independent testing has found that techniques like role-play framing and indirect phrasing can bypass guardrails on major commercial platforms, and output-side filters in particular have shown very low detection rates for harmful content that evades input screening. This is why guardrails are typically paired with continuous observability and testing rather than treated as a one-time fix.
Do AI guardrails slow down or limit what AI systems can do?
Well-designed guardrails aim to guide behavior without blocking legitimate use, similar to how a highway barrier doesn’t stop traffic from moving. In practice, though, testing shows that more aggressive filters can produce false positives, incorrectly blocking valid requests like code review or technical questions, so tuning the balance between safety and usability is an ongoing part of implementation.
Are AI guardrails required by law?
Requirements vary by jurisdiction and sector, but regulatory frameworks are increasingly pushing organizations toward guardrail-style controls, particularly around transparency, human oversight, and accountability. High-risk applications in finance, healthcare, and government are generally under the most pressure to implement documented, auditable guardrails.
Continue Exploring
AI guardrails work alongside AI observability, which detects when an AI system’s outputs go wrong, and are one of the practical responses to problems like model drift, where a model’s accuracy degrades over time. Further entries on MLOps, explainable AI, AI agents, and AI hallucination in this Computer Science series are on the way.
References and Further Reading
- Rebedea, T., Dinu, R., Sreedhar, M. N., Parisien, C., & Cohen, J. (2023). “NeMo Guardrails: A Toolkit for Controllable and Safe LLM Applications with Programmable Rails.” Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing: System Demonstrations, 431–445. https://aclanthology.org/2023.emnlp-demo.40/ (peer-reviewed conference paper)
- Gunasekara, L., El-Haber, N., Nagpal, S., Moraliyage, H., Issadeen, Z., Manic, M., & De Silva, D. (2025). “A Systematic Review of Responsible Artificial Intelligence Principles and Practice.” Applied System Innovation, 8(4), 97. https://doi.org/10.3390/asi8040097 (peer-reviewed journal)
- Ayyamperumal, S. G., & Ge, L. (2024). “Current state of LLM Risks and AI Guardrails.” arXiv:2406.12934 (preprint). https://arxiv.org/abs/2406.12934
- IBM. “What Are AI Guardrails?” https://www.ibm.com/think/topics/ai-guardrails
- Unit 42, Palo Alto Networks. “How Good Are the LLM Guardrails on the Market? A Comparative Study on the Effectiveness of LLM Content Filtering Across Major GenAI Platforms.” https://unit42.paloaltonetworks.com/comparing-llm-guardrails-across-genai-platforms/
- National Institute of Standards and Technology (NIST). “AI Risk Management Framework.” https://www.nist.gov/itl/ai-risk-management-framework (U.S. government)
- Market.us. (2026). “AI Guardrails Market Size, Share.” https://market.us/report/ai-guardrails-market/ (industry market data)