
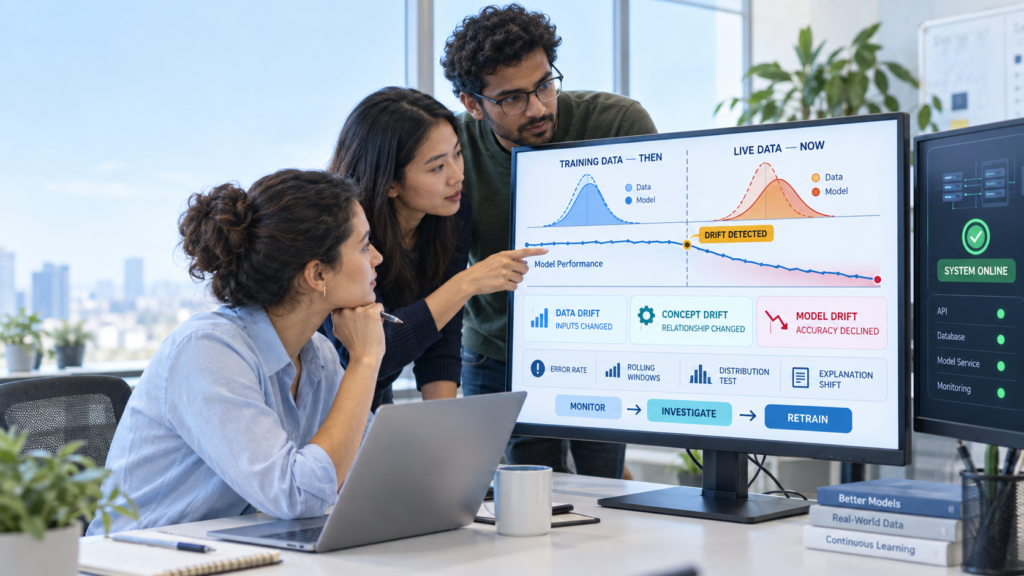
Model drift is the gradual decline in a machine learning model’s predictive accuracy that happens when the statistical relationship between its inputs and the real world changes after the model was trained. In plain terms: your model was trained on yesterday’s world, and today’s world has quietly moved on without it.
Model drift is one of the specific failure modes that AI observability exists to catch — because a drifting model rarely crashes or throws an error. It just gets steadily, silently worse at its job.
Model drift is a decades-old concept in statistics and machine learning, but it is receiving renewed attention as organizations scale up large language models and AI agents in production. It now sits inside the broader AI observability buildout — a market SNS Insider values at roughly $2.71 billion in 2025, growing toward $20.52 billion by 2035 — as vendors race to build drift-detection features specifically for generative AI systems, where “correct” output is harder to define than in classic predictive models.[9]
What Is Model Drift?
Every machine learning model is trained on a snapshot of the world captured in its training data. Model drift happens when the live world stops matching that snapshot — customer behavior shifts, a market changes, an adversary adapts — and the model, which has no way of knowing this on its own, keeps making predictions as if nothing changed. The foundational academic definition, from a widely cited 2014 survey in ACM Computing Surveys, describes this formally as drift occurring “when the joint probability distribution p(X, y)” — the relationship between the input data X and the target y the model predicts — “changes” between the time a model was trained and the time it’s used.[1]
Model Drift vs. Concept Drift vs. Data Drift: What’s the Difference?
These three terms are often used loosely, but the distinction matters for how you fix the problem. Concept drift is a change in the relationship itself — the same inputs now genuinely mean something different (the 2014 survey formally splits this into “real” concept drift, where the underlying decision boundary changes, versus “virtual” drift, where only the input distribution shifts without changing what it predicts).[1] Data drift is broader still: it can include concept drift, but also covers infrastructure changes, schema changes, or simply new categories of input the model never saw during training. Model drift is the observable symptom of either — the measurable decline in the model’s own accuracy, however it was caused.
Why Does Model Drift Matter?
Left undetected, model drift erodes the value of a deployed model in ways that are easy to miss precisely because nothing “breaks.” Two commonly cited examples illustrate this well. A retail model that predicts weekly sales from advertising and promotions can perform well at launch and then quietly degrade as seasonal shopping behavior shifts, if it was never trained to account for the season. A phishing-detection model trained to catch obvious red flags like “you’ve won a lottery” can lose effectiveness as attackers evolve their phrasing to sound legitimate, even though the underlying intent to deceive hasn’t changed at all.
The stakes compound with scale: a drifting fraud model quietly approves more bad transactions every day it goes unchecked, and a drifting recommendation model steadily erodes engagement in ways that a quarterly business review, not a real-time alert, is usually what finally catches.
How Is Model Drift Detected?
Detection methods generally fall into four families. Sequential error-tracking methods such as DDM (Drift Detection Method) and EDDM watch a model’s error rate — or the distance between its errors — and raise a warning once it crosses a statistical threshold.[1] Windowed comparison methods such as ADWIN keep a rolling window of recent predictions and compare its statistical properties against older data, flagging a change when the two windows diverge significantly.[1] Distribution-testing methods, such as KSWIN, apply formal statistical tests (like the Kolmogorov–Smirnov test) directly to the incoming data distribution. And explainability-based methods are a more recent addition: a 2023 peer-reviewed study demonstrated that tracking how a model’s own SHAP explanation values shift over time — without needing any new labeled data — could detect drift with better than 90% accuracy in a cybersecurity use case, which matters because labeled ground truth is often unavailable or delayed in live production systems.[2]
How Can Model Drift Be Prevented or Managed?
Because drift is a moving target by definition, “prevention” really means building a response system rather than a one-time fix. The literature on concept drift adaptation describes several standing strategies: retraining on a sliding window of only the most recent data, so old and possibly obsolete patterns gradually lose influence; blind adaptation, where a model is continuously retrained on new data on a fixed schedule regardless of whether drift has been explicitly detected; informed adaptation, where retraining is triggered only when a detector actually flags a change; and ensemble methods that maintain multiple models trained on different time windows, weighting each one dynamically as conditions change.[1] Which strategy fits depends on how fast the underlying pattern actually changes and how costly a false alarm is compared to a missed one.
Key Takeaways
- Model drift is the decline in a model’s real-world accuracy that happens when the statistical relationship it learned during training no longer matches current conditions.
- Concept drift (a genuine change in what the data means) and data drift (a broader category including schema, infrastructure, and input changes) are two distinct causes; model drift is the accuracy decline you actually observe.
- Detection methods fall into four families: error-rate tracking (DDM, EDDM), windowed statistical comparison (ADWIN), distribution testing (KSWIN), and newer explainability-based methods that work without labeled data.
- Common adaptation strategies include sliding-window retraining, scheduled (“blind”) retraining, detector-triggered (“informed”) retraining, and ensembles of models trained on different time periods.
- Model drift is a specific, well-studied failure mode that broader AI observability practice is built in part to catch, since a drifting model typically shows no errors, crashes, or alerts on its own.
Frequently Asked Questions
Is model drift the same as data drift?
No. Data drift is the broader category — any change in incoming data, including schema or infrastructure changes — while model drift specifically refers to the resulting decline in a model’s predictive accuracy. Data drift can cause model drift, but a model can also drift for other reasons, such as concept drift in what the data actually means.
How often should a model be retrained to prevent drift?
There’s no universal schedule — it depends on how quickly the underlying pattern changes and how costly errors are. Fast-moving domains like fraud detection or ad targeting may need frequent or continuously triggered retraining, while more stable domains might only need periodic review. Detection methods that trigger retraining automatically when drift is actually measured are generally more efficient than a fixed calendar schedule.
Can model drift happen without any error in the code?
Yes, and this is what makes it dangerous. The model, the pipeline, and the infrastructure can all be functioning exactly as designed while the model still produces increasingly wrong answers, because the real world it’s predicting has changed. This is why drift requires dedicated statistical monitoring rather than conventional error-based alerting.
Continue Exploring
Model drift is one of the specific problems that AI observability is designed to catch in production AI systems. Further entries on MLOps, explainable AI, and AI agents in this Computer Science series are on the way.
References and Further Reading
- Gama, J., Žliobaitė, I., Bifet, A., Pechenizkiy, M., & Bouchachia, A. (2014). “A survey on concept drift adaptation.” ACM Computing Surveys, 46(4), Article 44. https://doi.org/10.1145/2523813 (peer-reviewed journal)
- Lee, Y., Lee, Y., Lee, E., & Lee, T. (2023). “Explainable Artificial Intelligence-Based Model Drift Detection Applicable to Unsupervised Environments.” Computers, Materials & Continua, 76(2), 1701–1719. https://doi.org/10.32604/cmc.2023.040235 (peer-reviewed journal)
- Arize AI. “When I Drift, You Drift, We Drift.” https://arize.com/blog/model-concept-data-drift/
- Deepchecks. “Data Drift vs. Concept Drift: What Are the Main Differences?” https://deepchecks.com/data-drift-vs-concept-drift-what-are-the-main-differences/
- Splunk. “Model Drift: What It Is & How To Avoid Drift in AI/ML Models.” https://www.splunk.com/en_us/blog/learn/model-drift.html
- IBM. “Drift detection overview.” https://www.ibm.com/docs/SSQNUZ_4.0/wsj/model/wos-behavior-overview.html
- SNS Insider. (2026). “AI Observability Market Projected to Hit $20.52 Billion by 2035.” Market report via GlobeNewswire (industry market data)